Published 2026-09-14 · updated 2026-09-25 — part of an ongoing build diary of dated, real measurements, not a one-time proof of the platform's superiority.
A third, genuinely different model: Kimi-K3
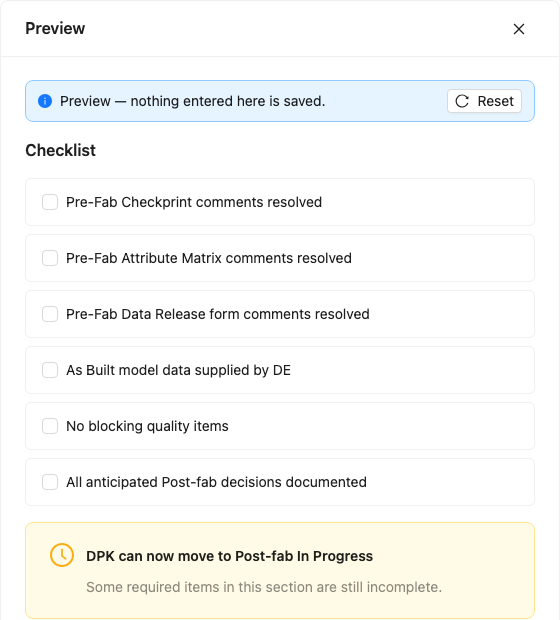
Qwen3.7 is one model family. To test whether the pattern above holds for a real architectural difference, not just another Qwen size, the same text-prompt spec was run against Kimi-K3 (Moonshot AI, via the same DashScope-compatible endpoint) — a reasoning model, unrelated to Qwen. Same rigor as every condition above: n=15 per condition, every run written to disk and type-checked, a Playwright-verified subset for clean render and correct DOM order, full screenshot galleries. Run 2026-08-30 against rebar-ui v0.1.0.
| Condition | Mean | Median | Min | Max | Std. dev. | Success |
|---|---|---|---|---|---|---|
| antd | 5,967 | 5,931 | 3,520 | 9,456 | 1,821 (30.5%) | 15/15 |
| rebar-ui | 1,925 | 1,889 | 1,578 | 2,869 | 278 (14.5%) | 15/15 |
| Wall-clock | Mean | Median | Min | Max | Std. dev. |
|---|---|---|---|---|---|
| antd | 160.0s | 155.6s | 70.0s | 261.5s | 56.2s (35.1%) |
| rebar-ui | 37.5s | 32.5s | 25.4s | 72.8s | 12.4s (33.0%) |
antd
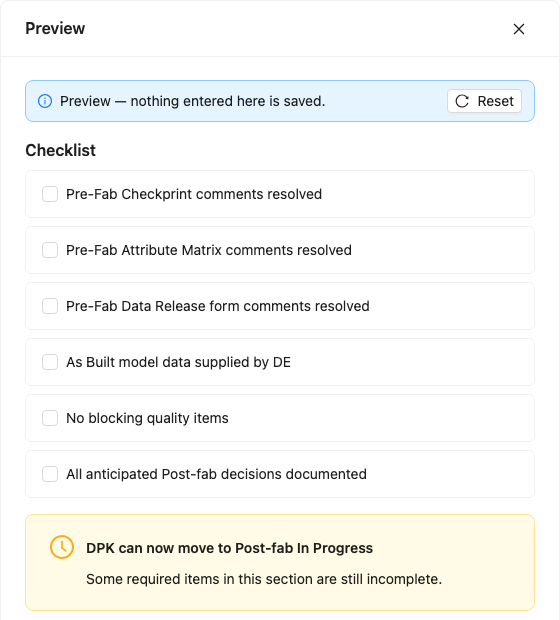
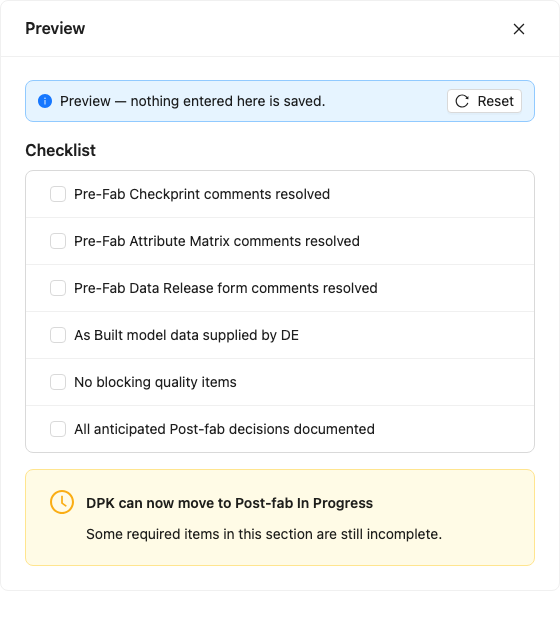
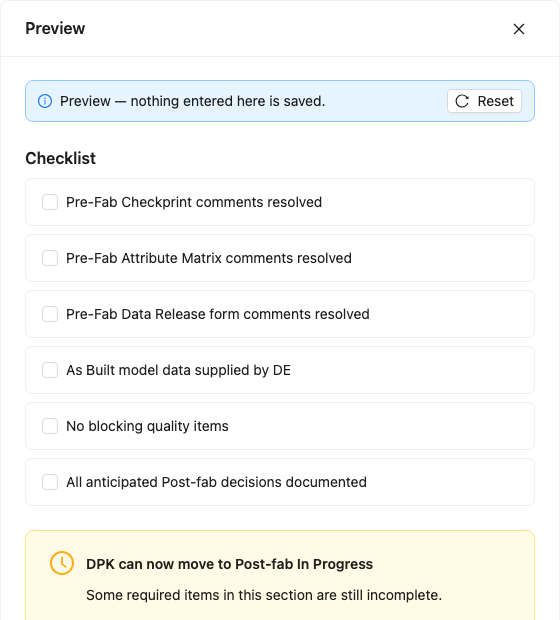
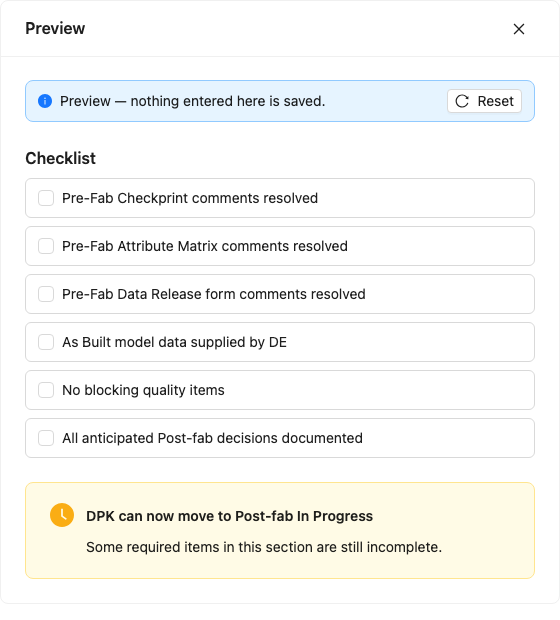
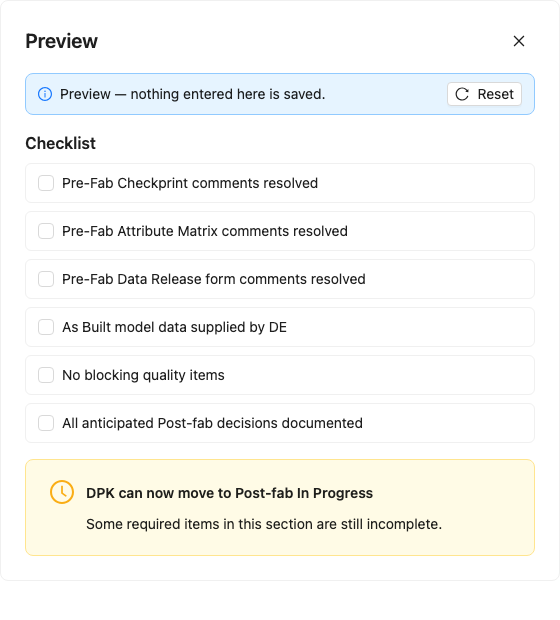
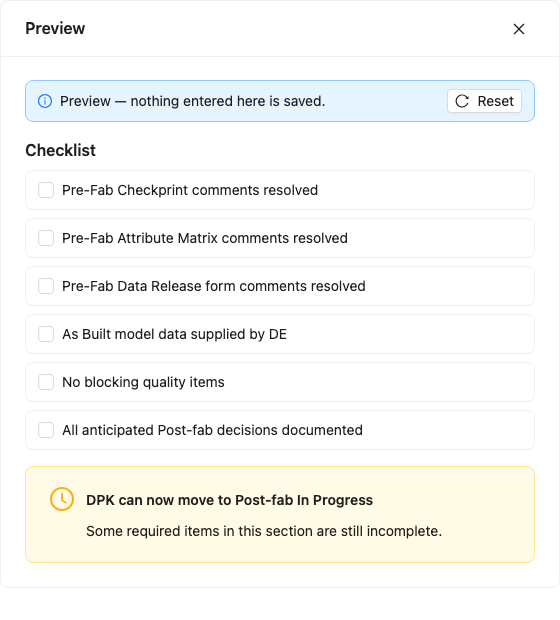
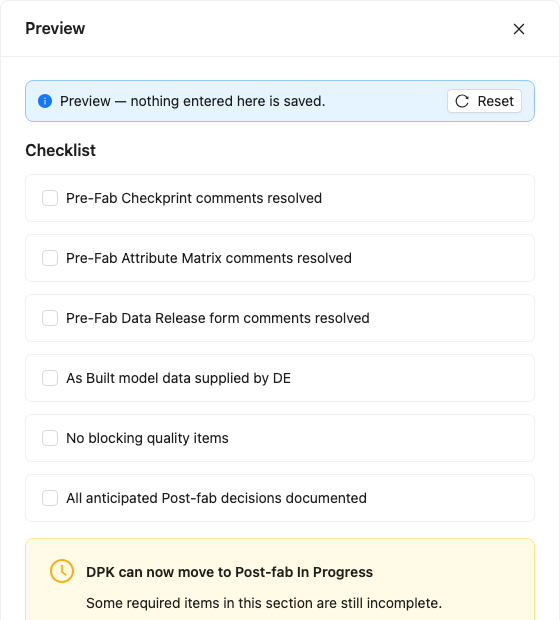
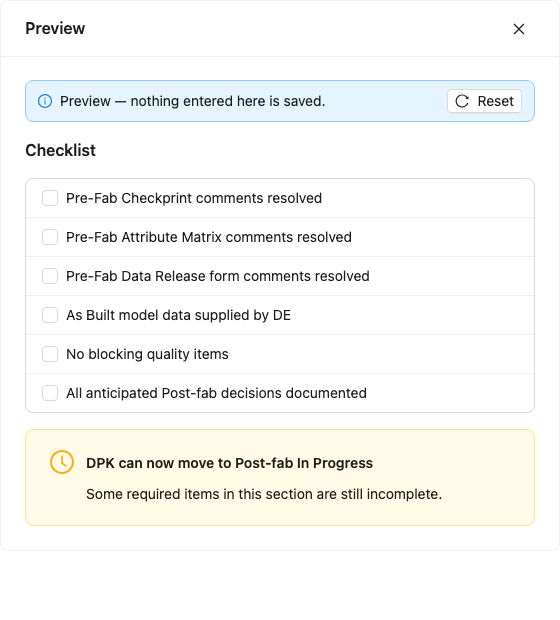
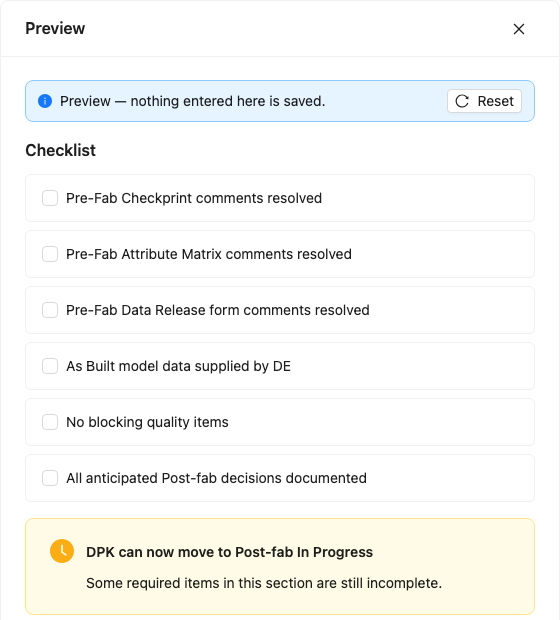
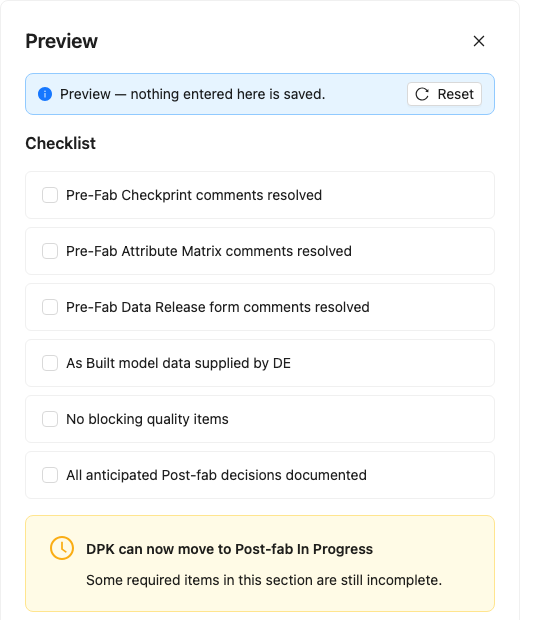
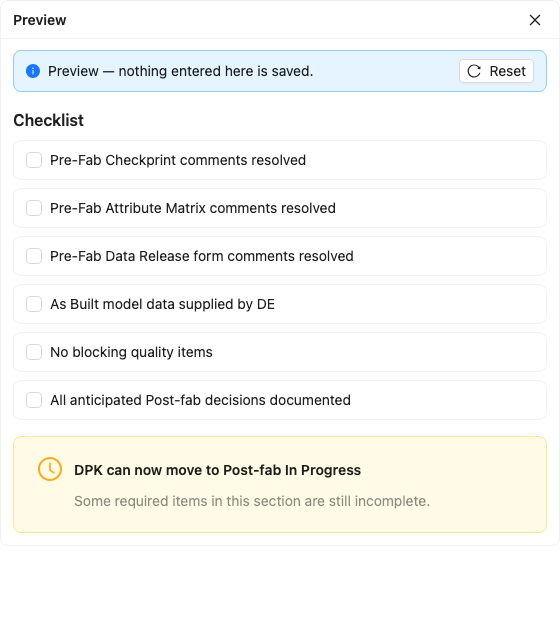
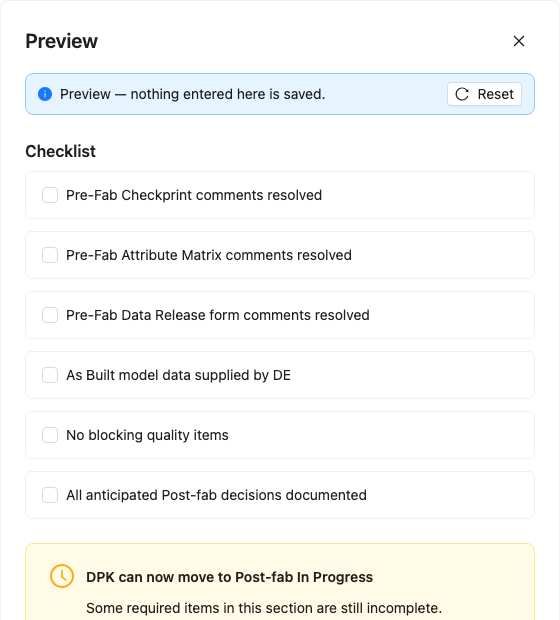
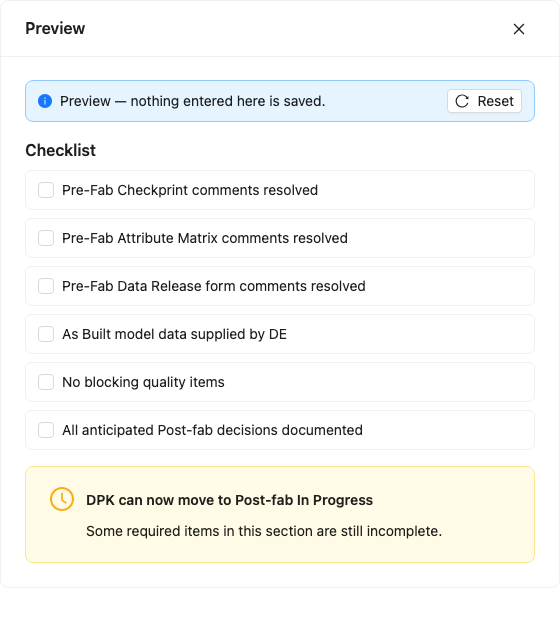
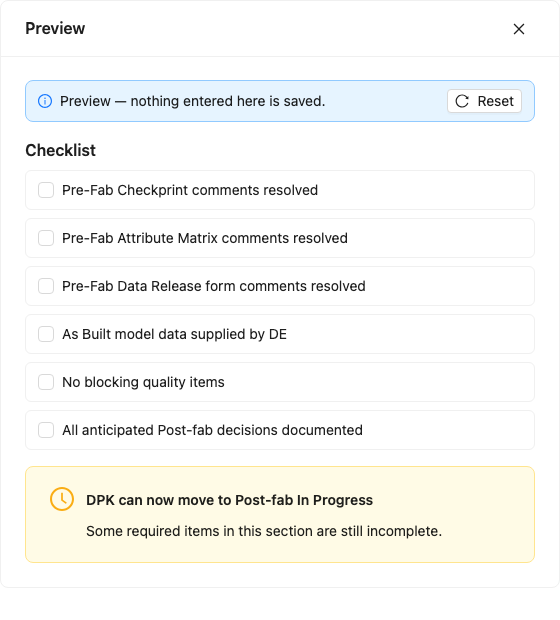
rebar-ui
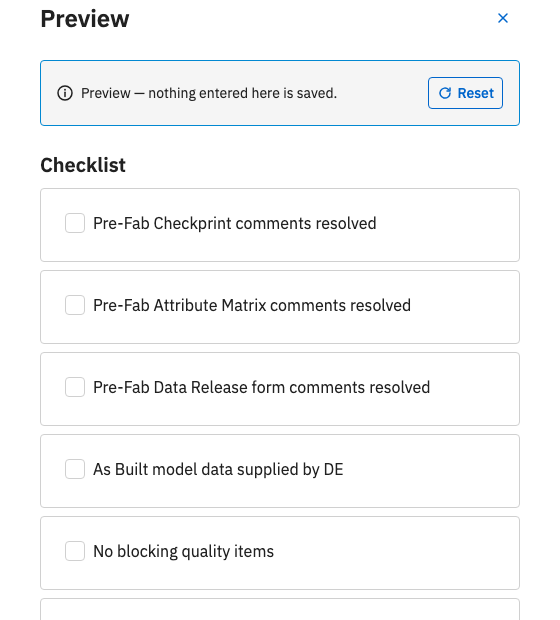
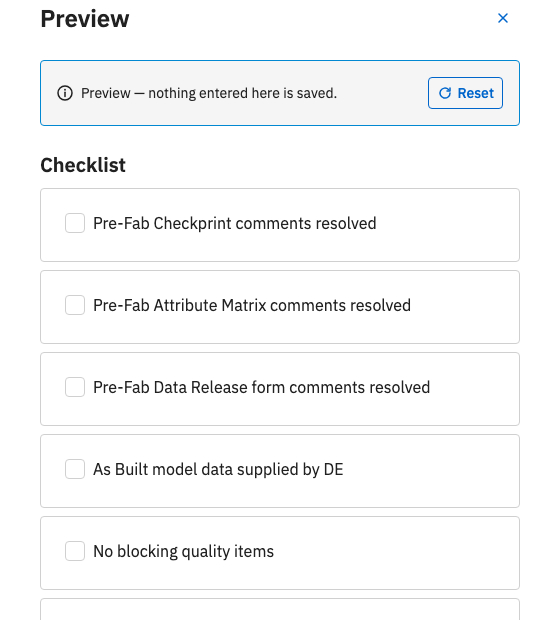
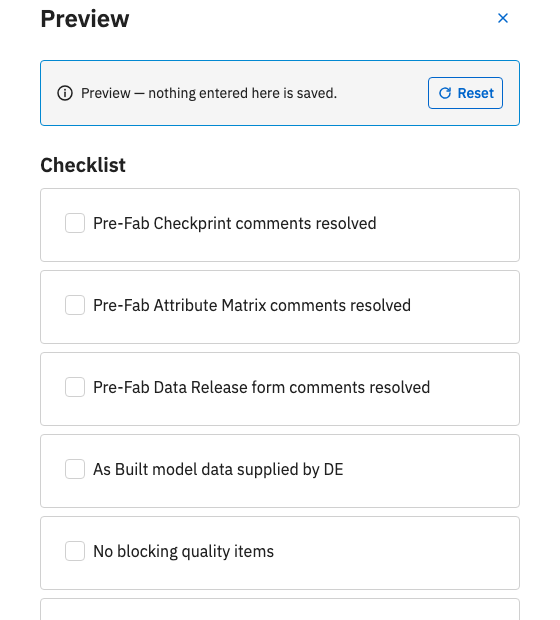
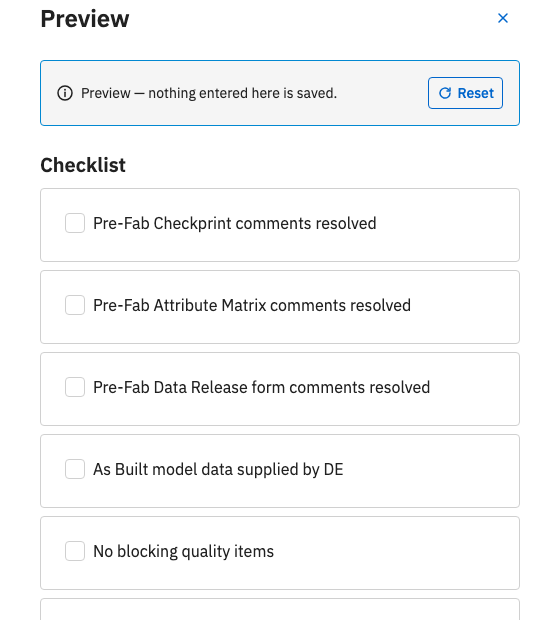
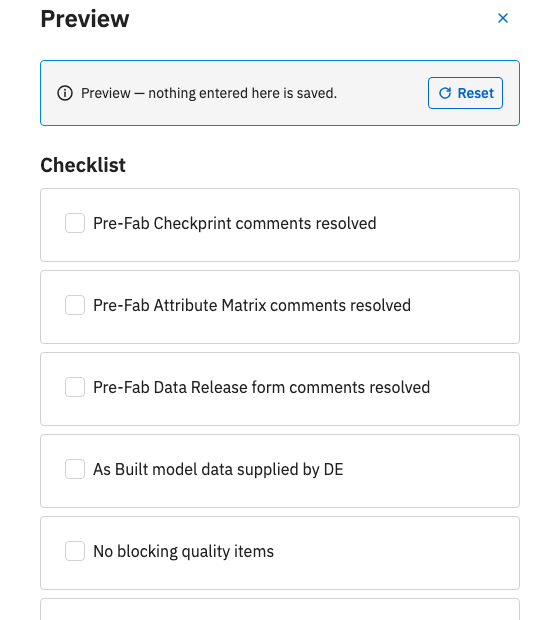
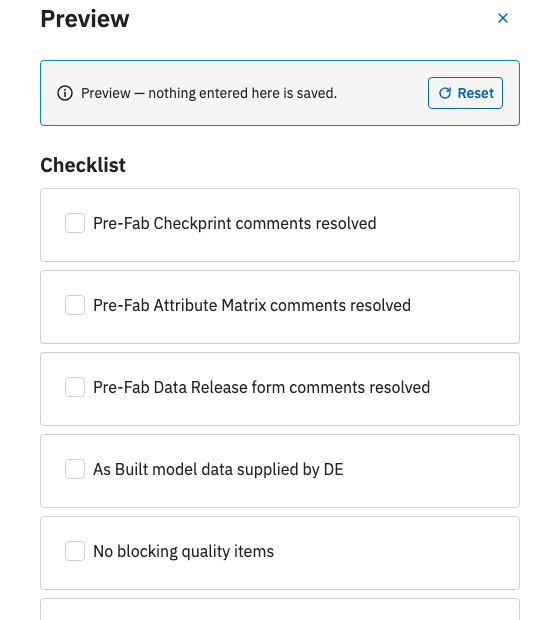
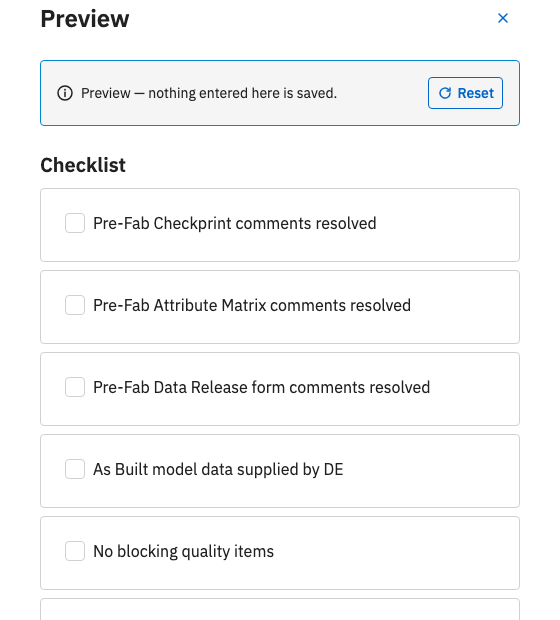
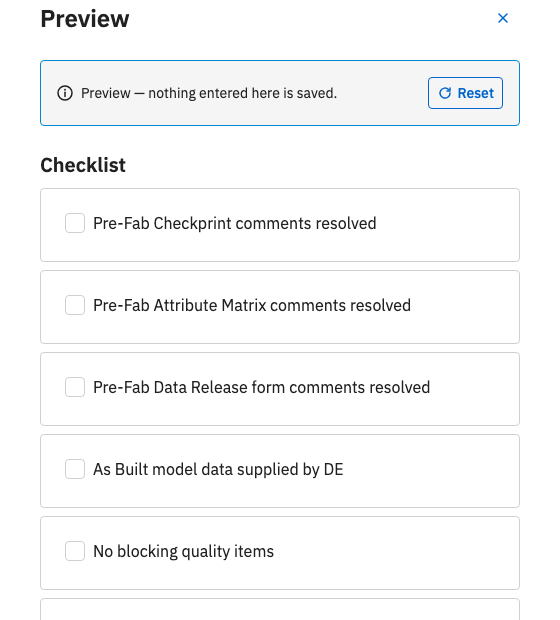
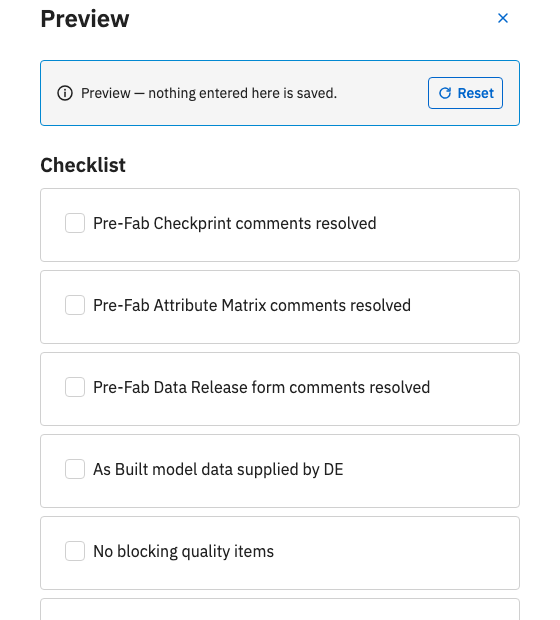
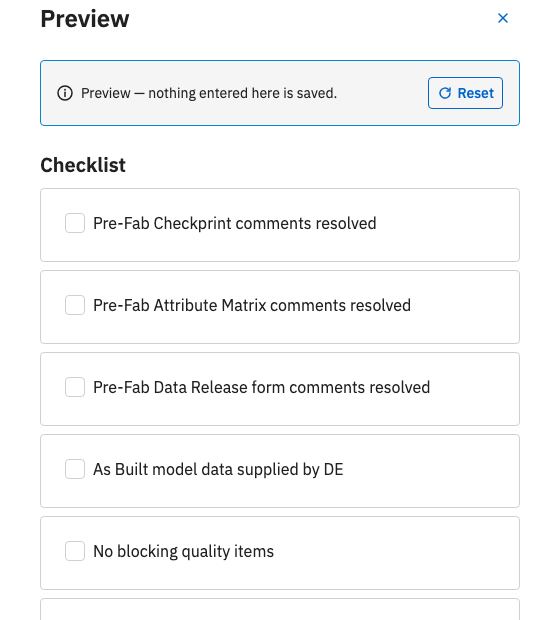
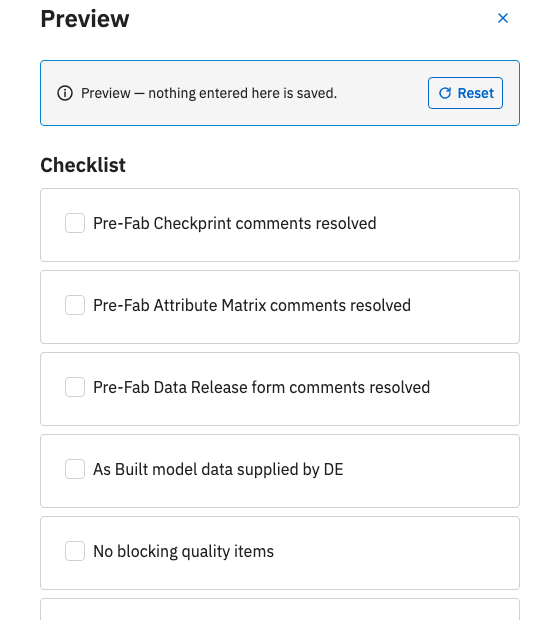
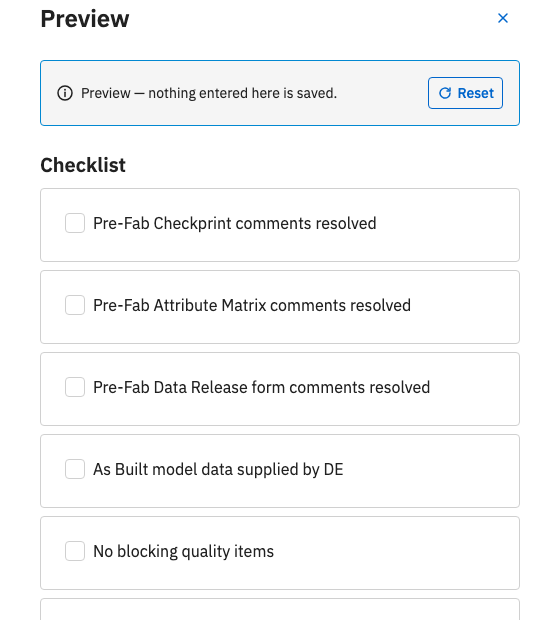
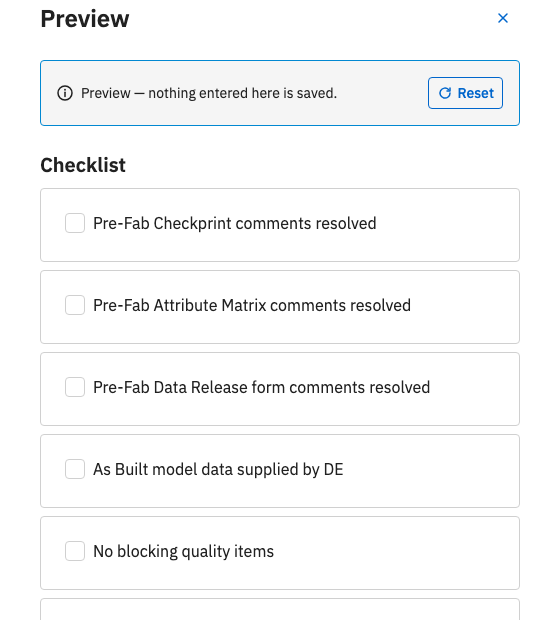
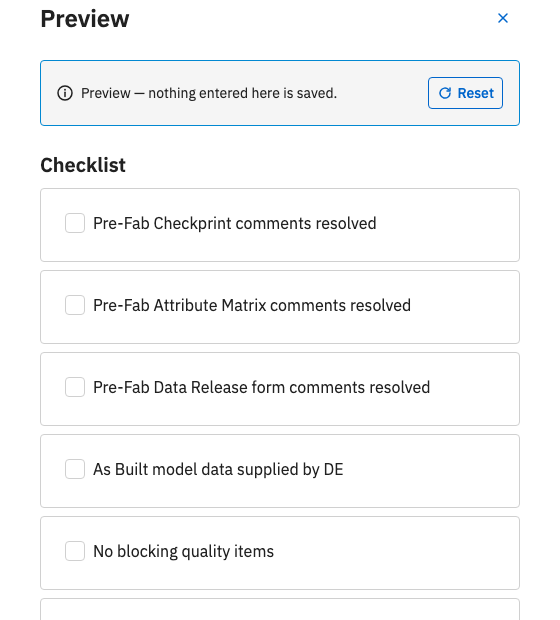
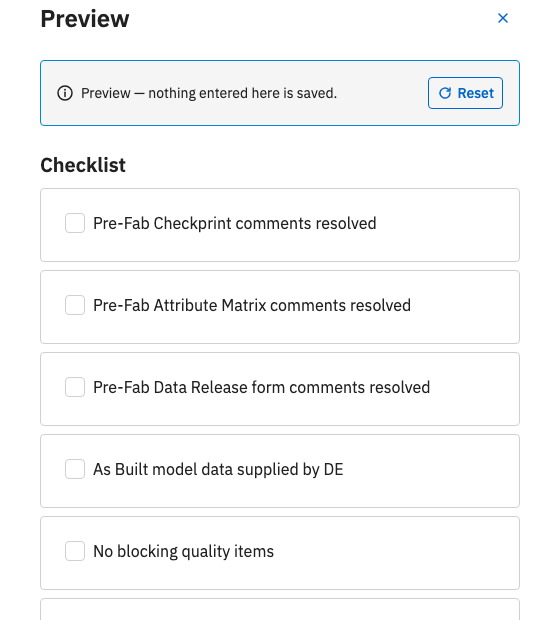
Caveats: n=15 per condition, 2026-08-30, same spec and blocks as the Claude and Qwen text-prompt experiments. Kimi-K3 was chosen after checking a couple of other third-party models reachable on the same platform — one produced no usable output at a normal token budget, another worked but cost noticeably more per call — so this is the one that held up. All 30 final runs typechecked and a Playwright-verified subset confirmed clean render and correct DOM order. antd's output shows the same deprecated Alert message prop found on every other antd condition on this page — harmless to rendering, a sign of antd v6 API drift the model's training hasn't caught up to.