Published 2026-09-14 · updated 2026-09-25 — part of an ongoing build diary of dated, real measurements, not a one-time proof of the platform's superiority.
Qwen3.7 (n=15 per condition)
Same spec, same blocks, same rigor — run against Qwen (qwen3.7-max for text, qwen3.7-plus for image) via the DashScope API, to test whether a cheaper model benefits even more from having layout/composition decisions removed from it. Run 2026-08-30 against rebar-ui v0.1.0.
Text prompt
| Condition | Mean | Median | Min | Max | Std. dev. | Success |
|---|---|---|---|---|---|---|
| antd | 3,388 | 2,989 | 1,597 | 6,446 | 1,376 (40.6%) | 15/15 |
| rebar-ui | 1,228 | 1,065 | 994 | 2,028 | 278 (22.6%) | 15/15 |
| Wall-clock | Mean | Median | Min | Max | Std. dev. |
|---|---|---|---|---|---|
| antd | 46.6s | 40.3s | 19.7s | 88.3s | 20.8s (44.6%) |
| rebar-ui | 10.3s | 9.4s | 6.0s | 21.7s | 3.9s (37.8%) |
antd
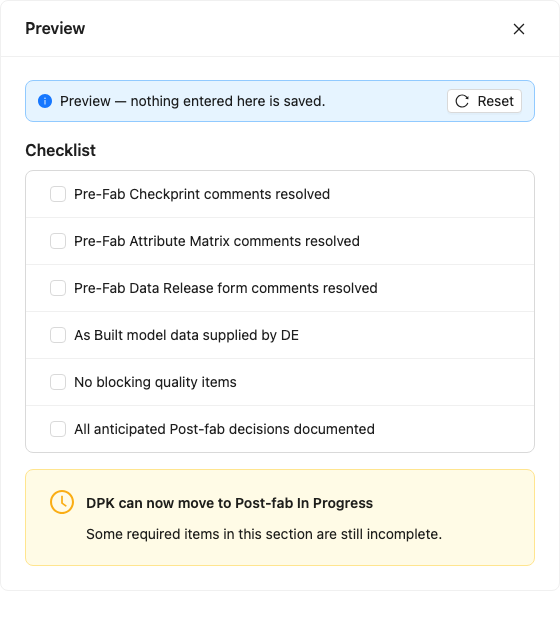
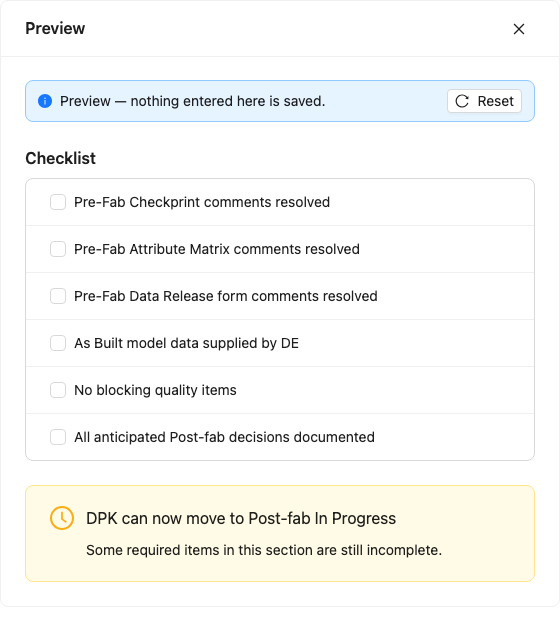
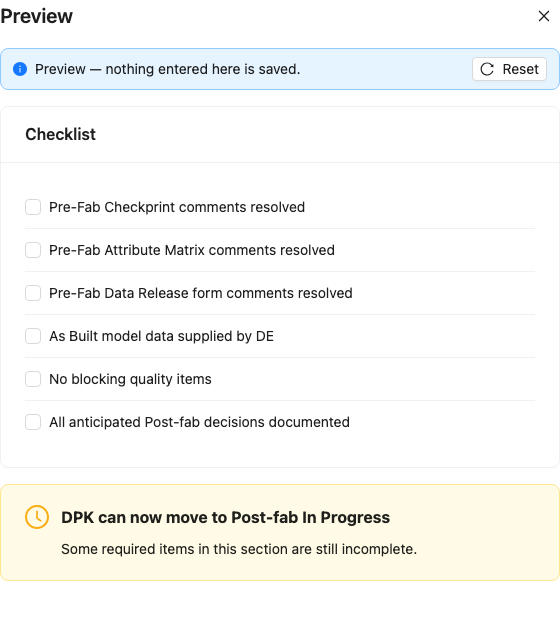
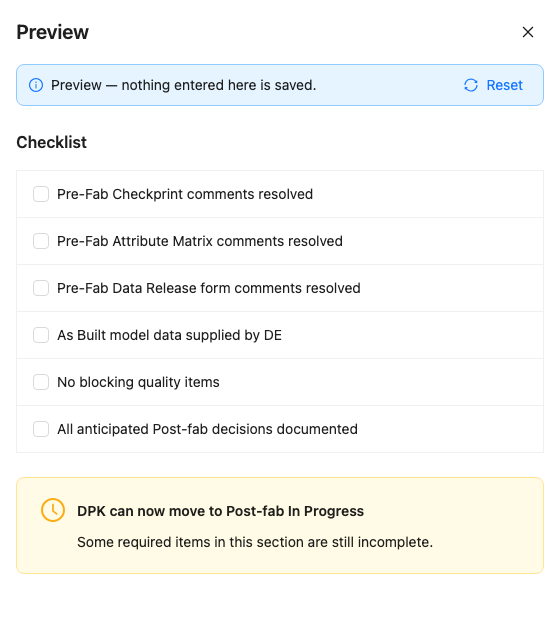
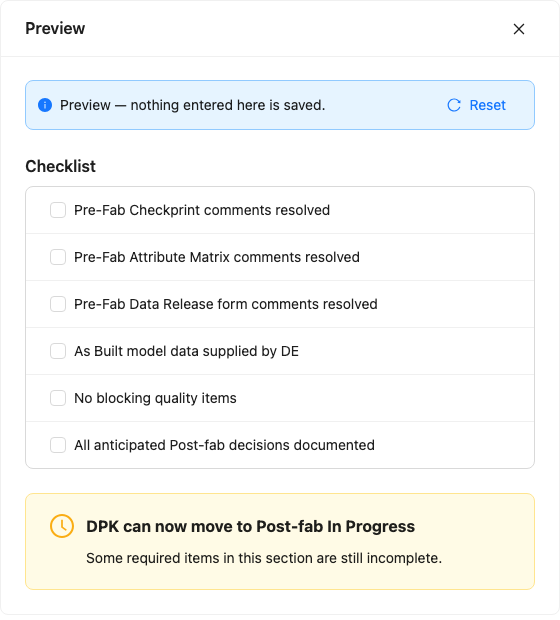
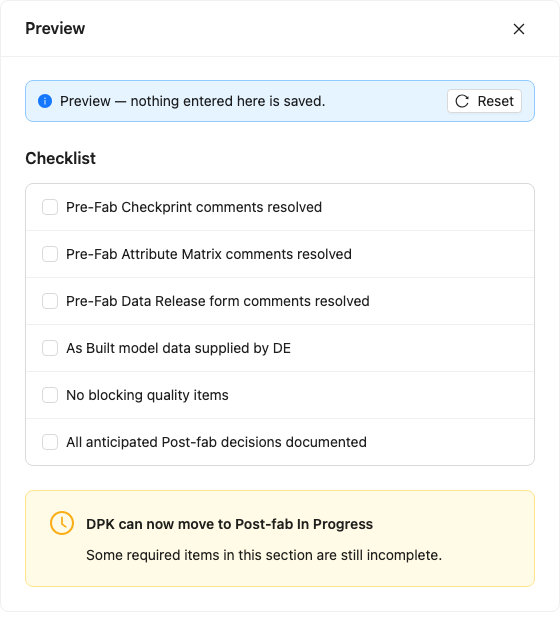
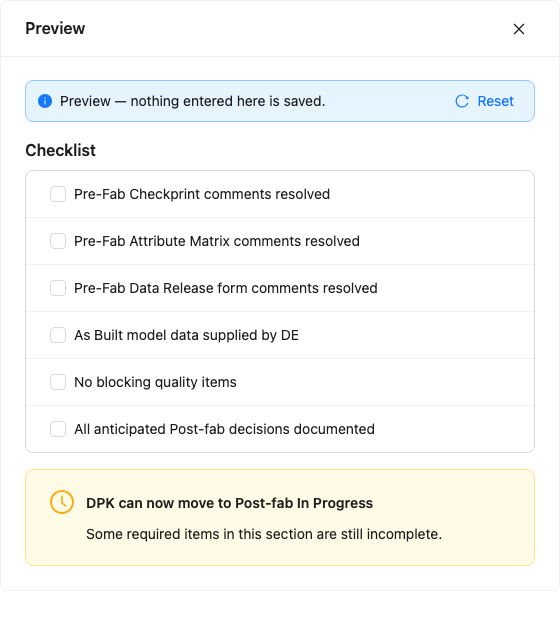
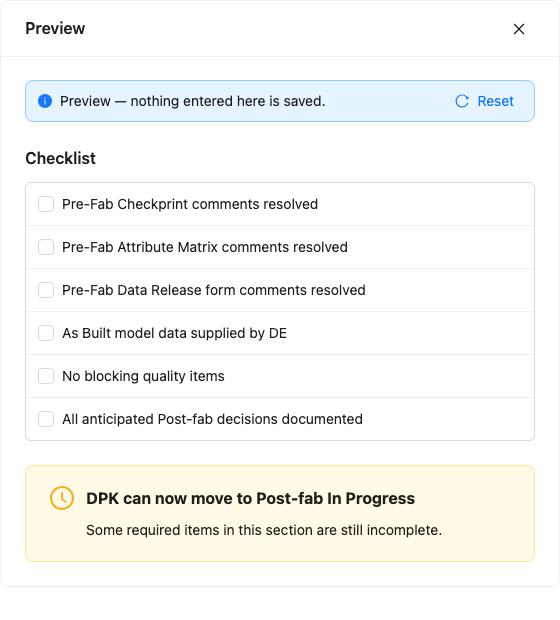
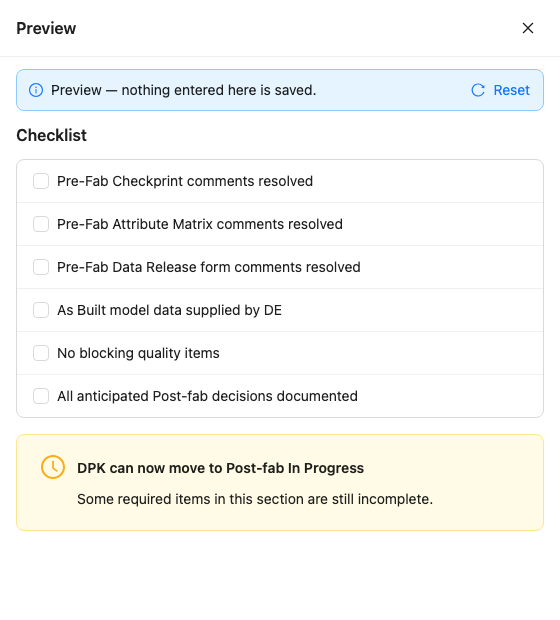
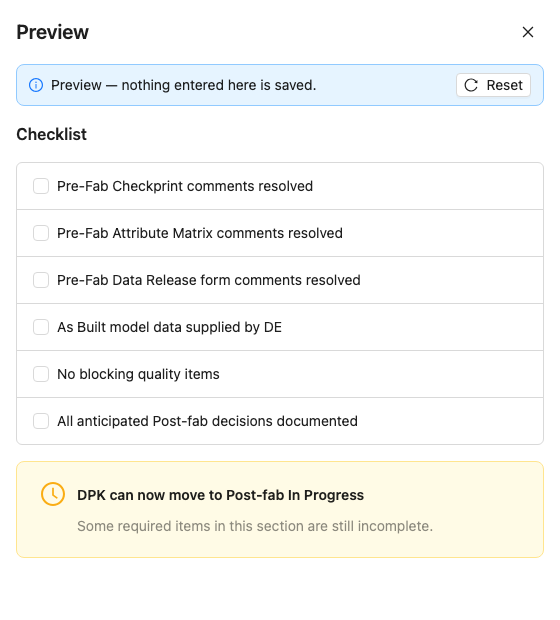
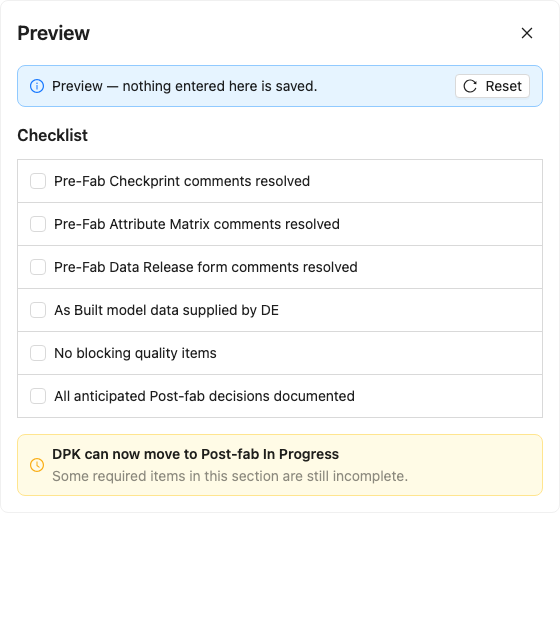
rebar-ui
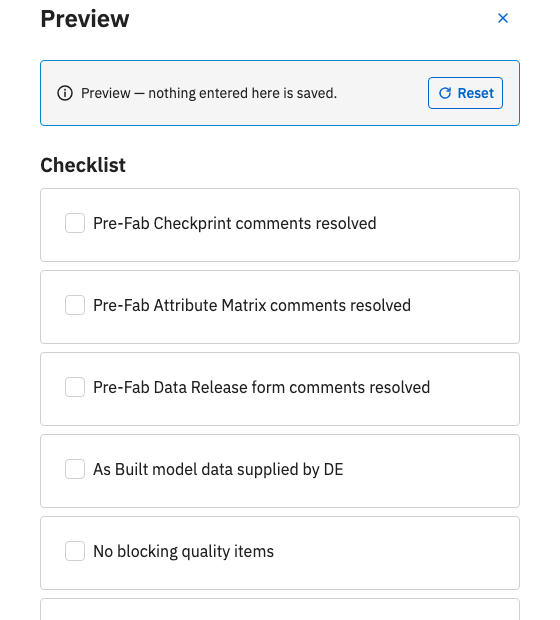
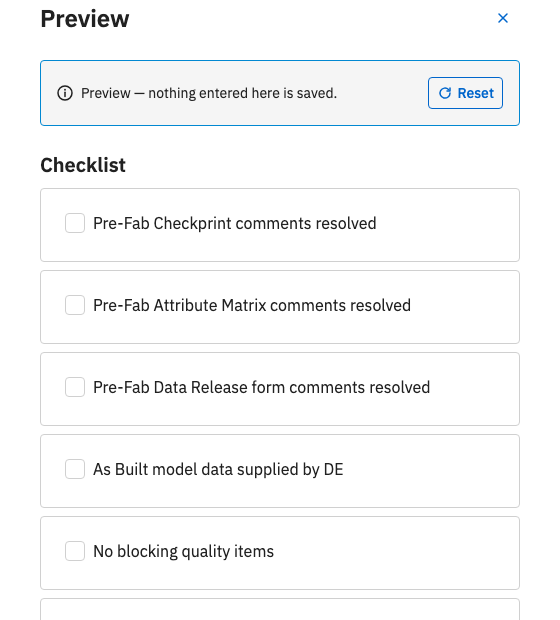
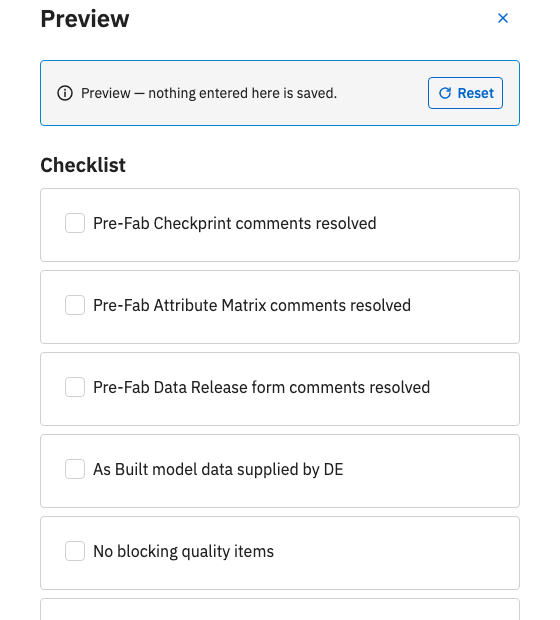
Image prompt
| Condition | Mean | Median | Min | Max | Std. dev. | Success |
|---|---|---|---|---|---|---|
| antd | 3,948 | 3,667 | 3,243 | 5,882 | 726 (18.4%) | 15/15 |
| rebar-ui | 2,956 | 2,965 | 2,839 | 3,129 | 90.3 (3.1%) | 15/15 |
| Wall-clock | Mean | Median | Min | Max | Std. dev. |
|---|---|---|---|---|---|
| antd | 33.2s | 29.2s | 20.5s | 64.6s | 11.9s (35.8%) |
| rebar-ui | 13.8s | 13.9s | 11.2s | 17.6s | 1.7s (12.1%) |
antd
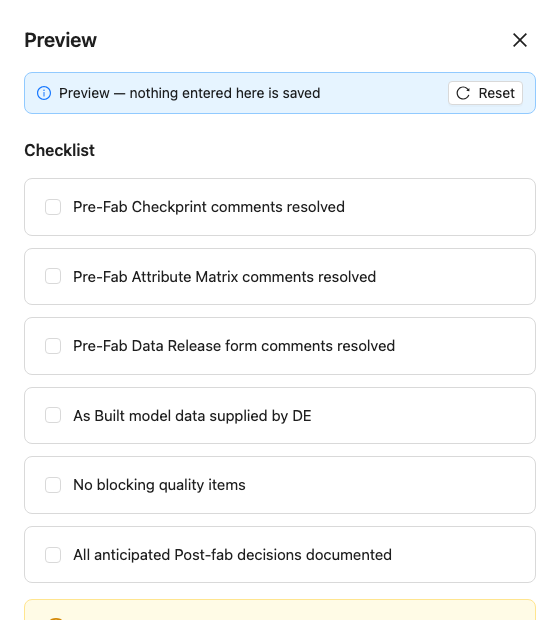
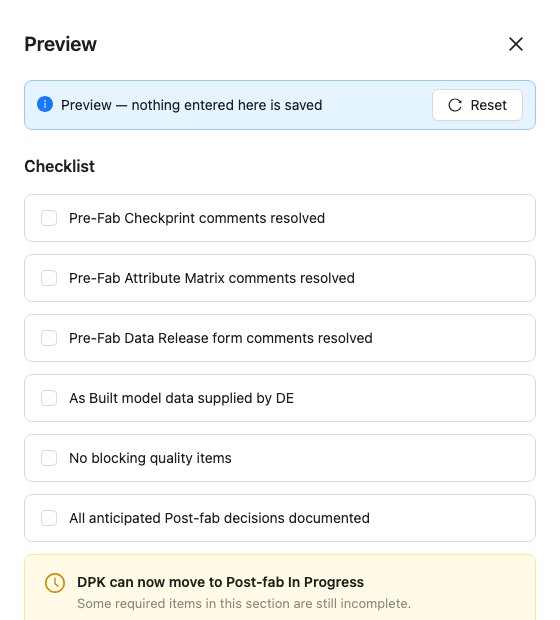
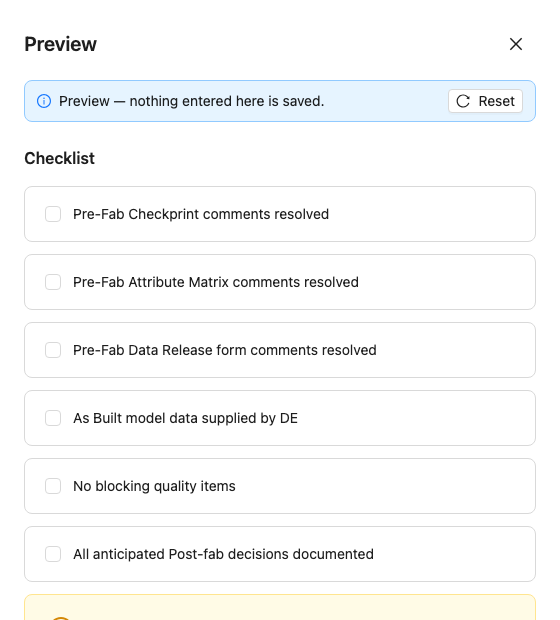
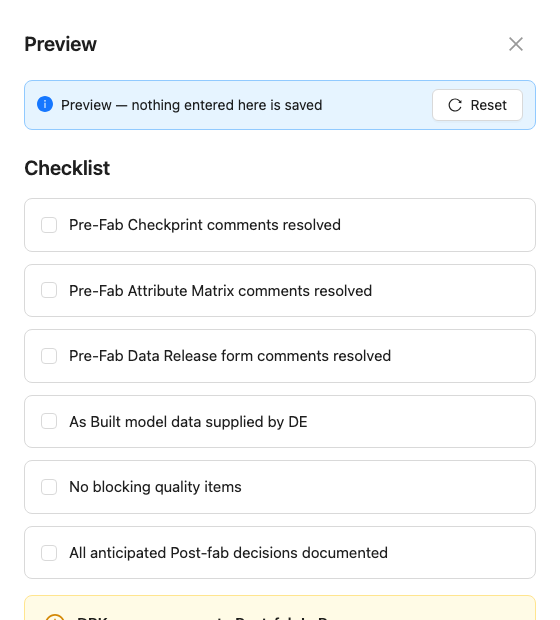
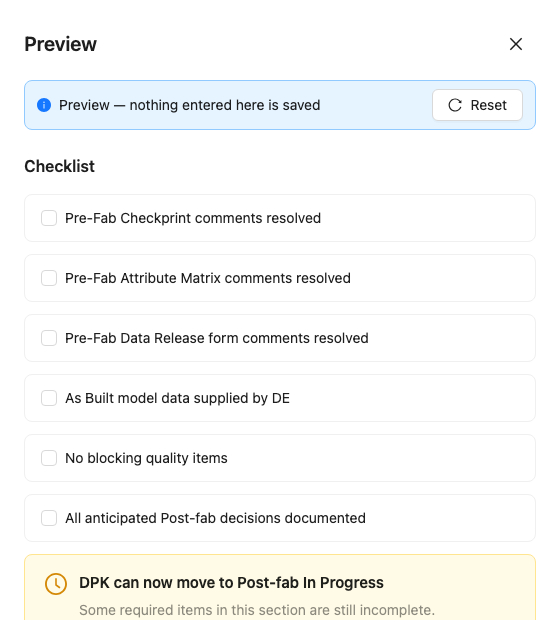
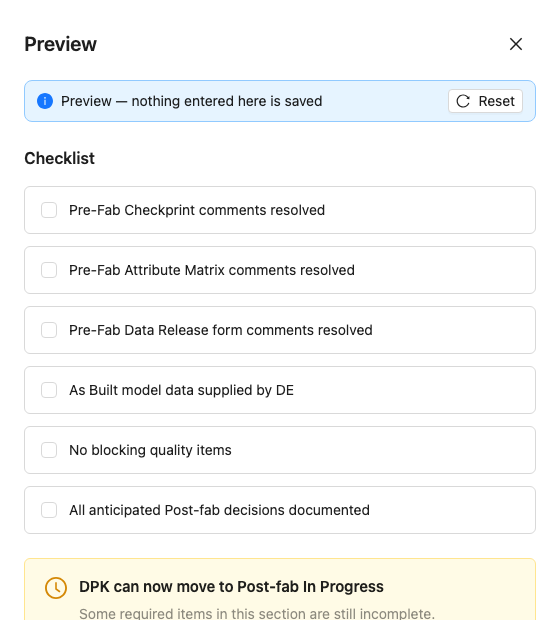
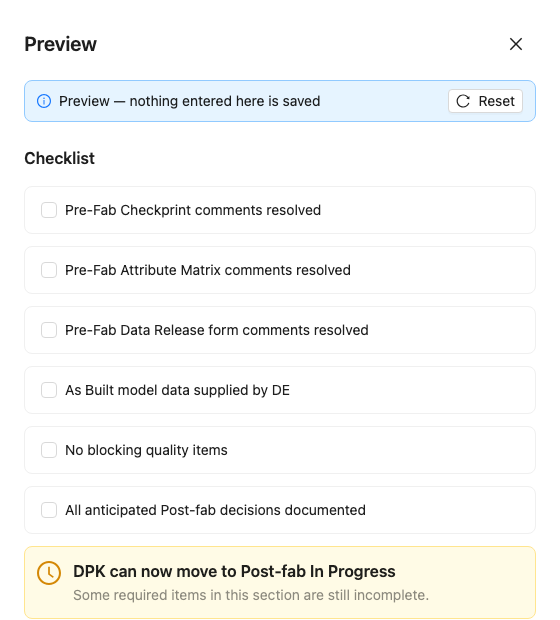
rebar-ui
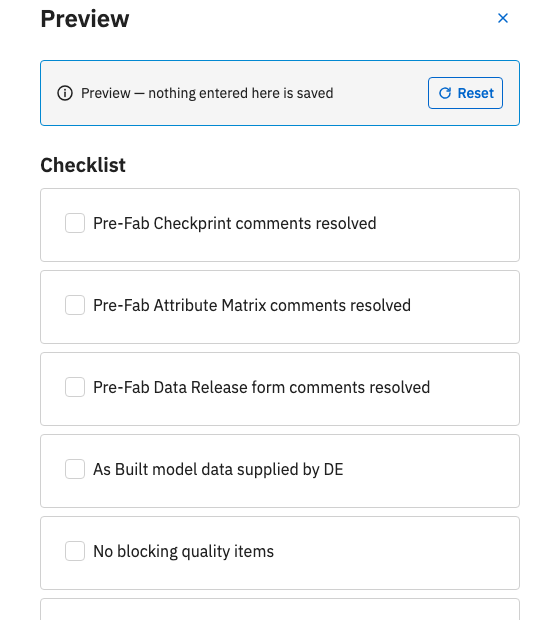
Caveats: n=15 per condition, one day (2026-08-29/30), same spec and blocks as the Claude experiments. All 60 runs were written to disk, type-checked, and a Playwright-verified subset confirmed clean render and correct DOM order for both extremes and the median per condition. All 60 were also screenshotted for the galleries above, using the same pixel-alignment method as the Claude galleries. antd's output shows the same deprecated Alert message prop found on Claude's antd runs. A prompt written for a general-purpose coding agent doesn't automatically work for a single completion call with no file access — one condition needed its prompt rewritten to be fully self-contained before all 15 runs passed cleanly; full account in ref/QWEN_BENCHMARK_PROTOCOL.md for anyone reproducing this.