Published 2026-09-14 · updated 2026-09-25 — part of an ongoing build diary of dated, real measurements, not a one-time proof of the platform's superiority.
Simple, Composite, Complex tiers
Three complexity tiers beyond the single fixed component in the receipts — text-prompt only, run against both Claude and Qwen. These specs needed six blocks not yet exercised above (form, table, data-list, filter-bar, tabs, modal), and Claude's numbers here are "marginal" — total tokens minus the ~20,644-token shared harness overhead every Claude Code session pays, so they're comparable in kind to Qwen's raw completion totals. Run 2026-08-30 against rebar-ui v0.1.0.
Claude (marginal tokens, n=5)
| Tier | Condition | Mean (marginal) | Difference |
|---|---|---|---|
| Simple | antd | 8,104 | — |
| rebar-ui | 7,999 | −1.3% | |
| Composite | antd | 8,591 | — |
| rebar-ui | 8,402 | −2.2% | |
| Complex | antd | 8,988 | — |
| rebar-ui | 8,712 | −3.1% |
Qwen (raw tokens, n=3-5)
| Tier | Condition | Mean | n | Difference |
|---|---|---|---|---|
| Simple | antd | 1,413 | 5 | — |
| rebar-ui | 1,269 | 5 | −10.2% | |
| Composite | antd | 2,138 | 4 | — |
| rebar-ui | 1,881 | 3 | −12.0% | |
| Complex | antd | 2,762 | 5 | — |
| rebar-ui | 1,794 | 5 | −35.0% |
One representative build per condition (final run of each n=5 batch)
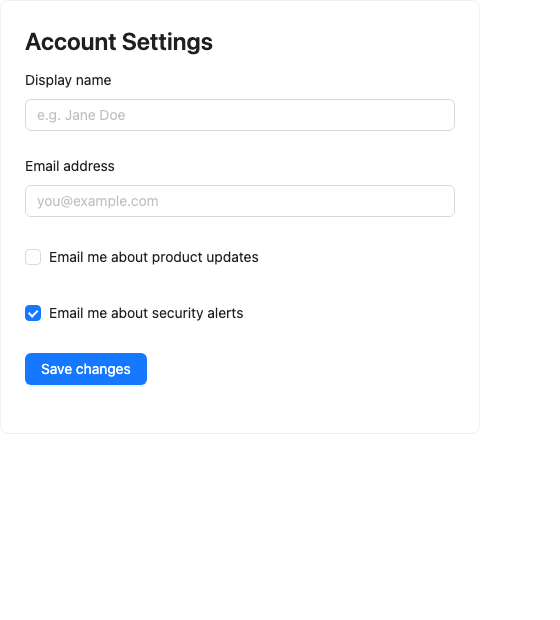
Claude · antd · Simple
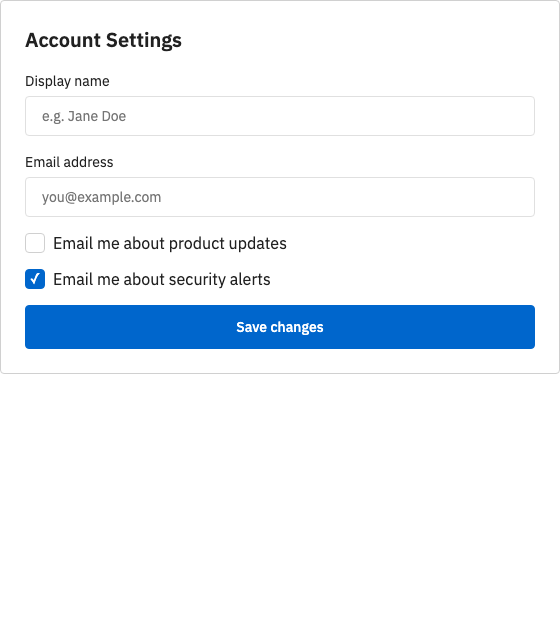
Claude · rebar-ui · Simple
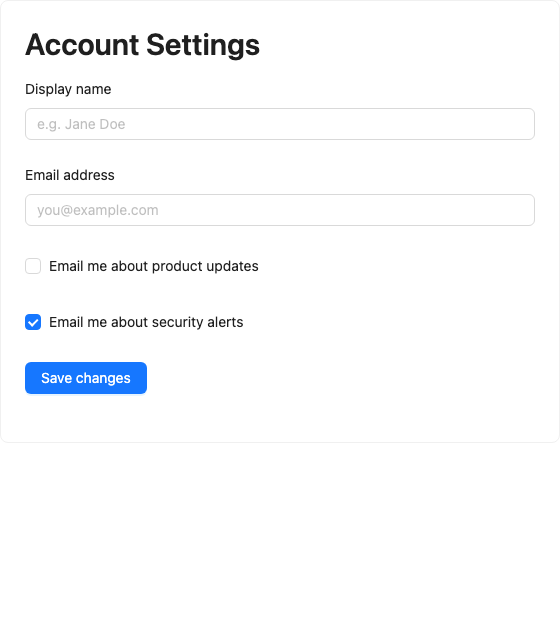
Qwen · antd · Simple
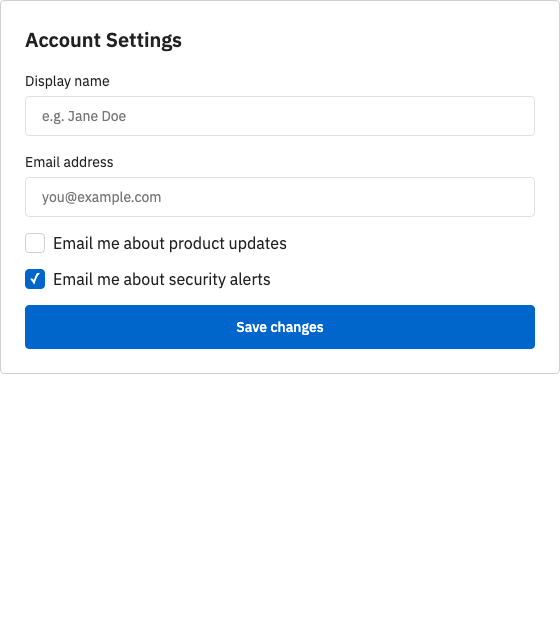
Qwen · rebar-ui · Simple
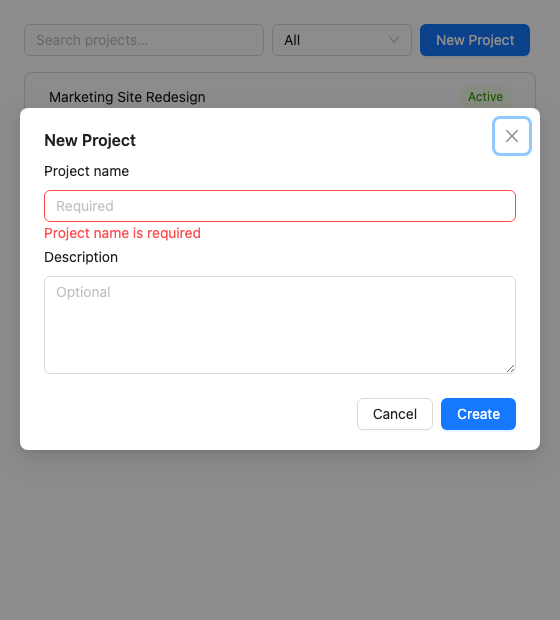
Claude · antd · Composite
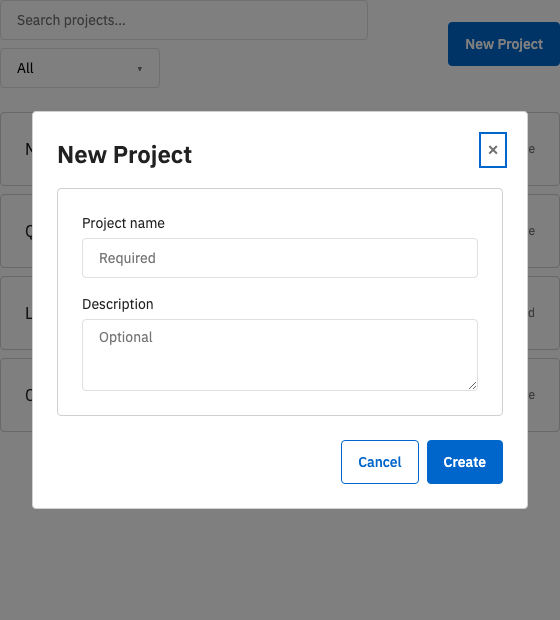
Claude · rebar-ui · Composite
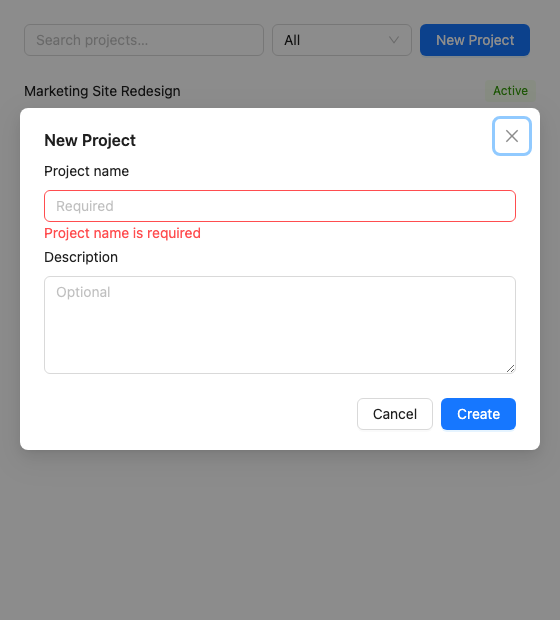
Qwen · antd · Composite
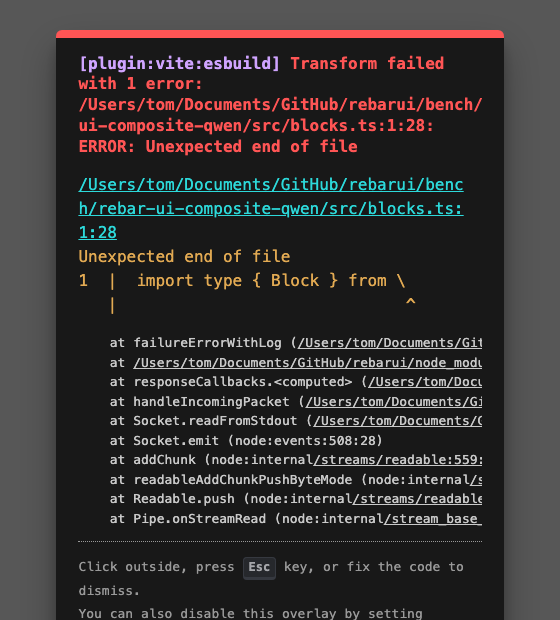
Qwen · rebar-ui · Composite
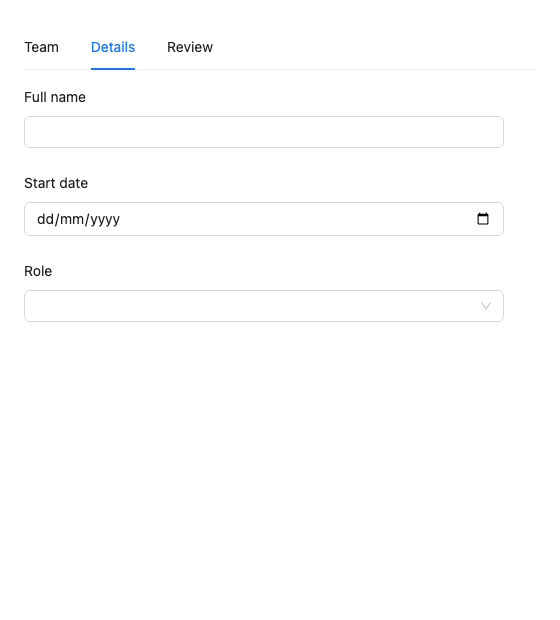
Claude · antd · Complex
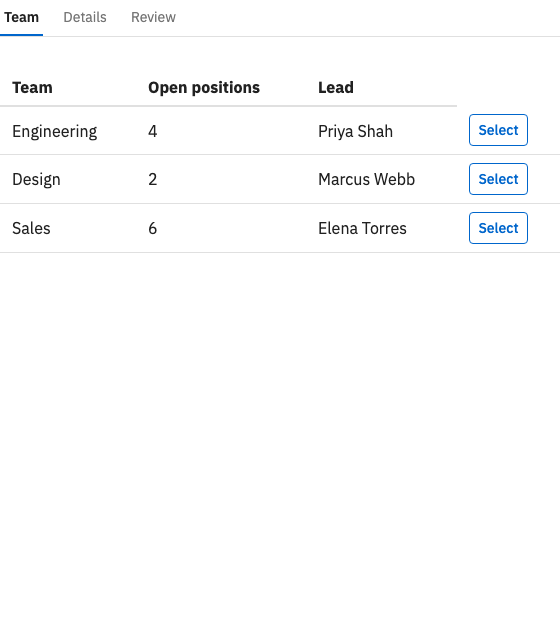
Claude · rebar-ui · Complex
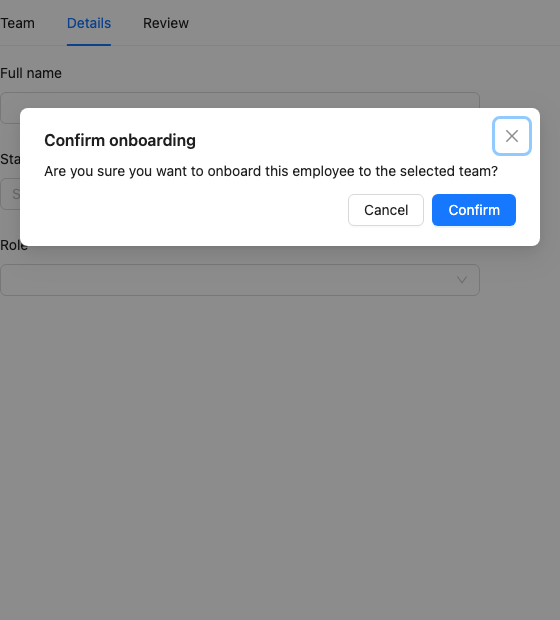
Qwen · antd · Complex
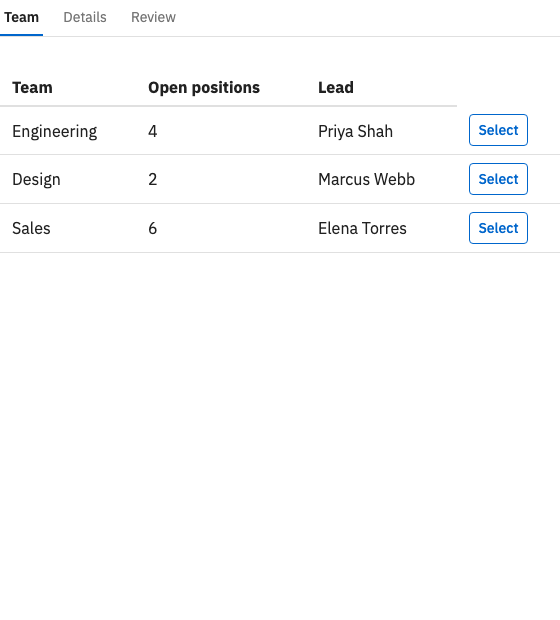
Qwen · rebar-ui · Complex
Caveats: n=5 per condition (n=3-4 for two Qwen composite cells), one day (2026-08-29/30). All builds typechecked and were Playwright-verified (clean render, zero console errors beyond antd's already-noted deprecation warning). Claude was instructed to build one-shot (no file exploration, no self-verification) each run, confirmed genuinely one-shot afterward (exactly one tool call per run), to mirror what Qwen's raw completion call structurally can't do either way.